

Standalone programs that convert transcripts from one tool format to another, e.g.
- trs - Transcriber transcripts
- eaf - ELAN files
- vtt - web subtitles (Web VTT)
- slt - SALT transcripts
- cha - CLAN CHAT transcripts
- textgrid - Praat TextGrids
- pdf - PDF files
- tex - LaTeX files
- txt - plain text files
- kaldi - input files for the Kaldi automatic speech recognition training system
| to↓ from→ | trs | eaf | vtt | slt | cha | textgrid | txt |
|---|---|---|---|---|---|---|---|
| trs | eaf-to-trs | vtt-to-trs | slt-to-trs | cha-to-trs | textgrid-to-trs | ||
| eaf | trs-to-eaf | vtt-to-eaf | slt-to-eaf | cha-to-eaf | textgrid-to-eaf | txt-to-eaf | |
| vtt | trs-to-vtt | eaf-to-vtt | slt-to-vtt | cha-to-vtt | textgrid-to-vtt | ||
| slt | trs-to-slt | eaf-to-slt | |||||
| cha | trs-to-cha | eaf-to-cha | vtt-to-cha | ||||
| textgrid | trs-to-textgrid | eaf-to-textgrid | vtt-to-textgrid | slt-to-textgrid | cha-to-textgrid | ||
| txt | trs-to-txt | ||||||
| trs-to-pdf | eaf-to-pdf | vtt-to-pdf | slt-to-pdf | cha-to-pdf | textgrid-to-pdf | ||
| tex | trs-to-tex | eaf-to-tex | vtt-to-tex | slt-to-tex | textgrid-to-tex | ||
| kaldi | trs-to-kaldi | eaf-to-kaldi | textgrid-to-kaldi |
These use the serializers/deserializers in the formatter directory of this repository to read a file in one format, convert it to an annotation graph, and then write that graph out as a file in another format. As pointed out by Cochran et al. (2007 - Report from TILR Working Group 1 : Tools interoperability and input/output formats) this saves having order n2 explicit conversion algorithms between formats; only 2n format conversions are required (as some of these formats above are output-only, it's actually less than 2n).
This exemplifies an approach to linguistic data interoperability called the interlingua philosophy on interoperability by Witt et al. (2009) and uses annotation graphs as an 'interlingua' similar to work by Schmidt et al. (2008), except that rather using a third file format as a persistent intermediary, the annotation graph models of the linguistic data are ephemeral, existing in memory only for the duration of the conversion.
As there is no persistent intermediate file, and many formats do not support the meta-data, annotation granularity or ontology of other formats, many of these conversions necessarily entail loss of data. However, mappings are made from one format to another wherever possible.
For notes about specific correspondences or data losses, use the --help command-line
switch, or use the Help|Information menu option of the conversion utility concerned.
The basic process of making a YouTube video corpus with TextGrid transcripts is:
- Download Youtube videos with their closed-caption subtitle files.
- Convert the closed-caption subtitle files to TextGrids.
There's a tool called yt-dlp which can be used for downloading videos from YouTube. It's a command-line program that can be given a URL for downloading. If the URL is a playlist, then it will download all videos in the playlist into separate files.
It has many useful command-line options:
--help- Displays information about all the other command-line options.-f- Sets the format for the video, e.g.-f wavshould download WAV files,mp4will download MP4's, etc.--extract-audio- Extracts the audio from the video after downloading it. This option is useful if-f wavdoesn't work because WAV is not available.--audio-format- Specifies what format to use if you're using--extract-audio--sub-lang- Downloads subtitle/closed-caption files for the given ISO language code. e.g.--sub-lang en-GBwill download British English subtitles. The subtitle files are saved in ...vtt files.
So for example the following command will download MP4 files and English closed-captions for the given playlist:
yt-dlp -f mp4 --sub-lang en https://www.youtube.com/playlist?list=PLdsZeeCVYnY3em55M2d3Iq3H-jSPLIWBF
...and the following will download WAV files instead of MP4 for the given playlist:
yt-dlp --extract-audio --audio-format wav --sub-lang en https://www.youtube.com/playlist?list=PLdsZeeCVYnY3em55M2d3Iq3H-jSPLIWBF
Caveat: There's a potential problem with using YouTube's automatically-generated captions; they often have a whole bunch of repeated phrases as it goes through the recording, so much of the resulting transcript is doubled up. So make sure you eyeball your TextGrids at the end to ensure the results are what you expect!
vtt-to-textgrid.jar is a utility for converting VTT files to TextGrids.
(If you prefer ELAN transcripts, try vtt-to-eaf.jar instead)
It's a Java program, so you must have a recent version of Java installed for it to work.
Downloading the vtt-to-textgrid.jar file and double-clicking it should work, but if not, you can run it from the command line like this:
java -jar vtt-to-textgrid.jar
When it starts, it looks like this:
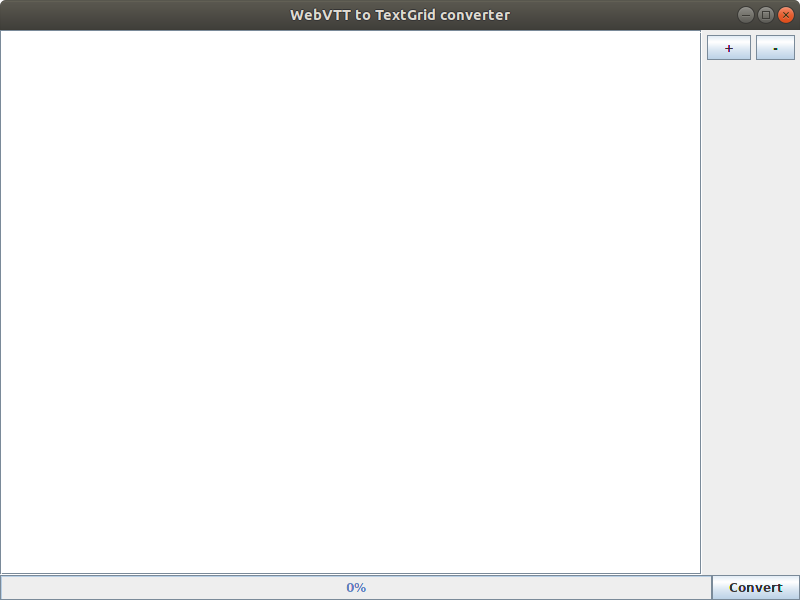
You need to drag/drop vtt files into the big white space (or use the + button), and then click Convert. This will save each TextGrid in the same folder as the VTT file.
To build all coverters and the documentation site for a release:
mvn clean package site site:deploy
All converters are then to be found in the bin subdirectory.
- In this directory, run the following command (change myannotator to the required name):
mvn archetype:generate \ -DgroupId=nz.ilbb.ag \ -DartifactId=informattooutformat \ -DarchetypeArtifactId=maven-archetype-quickstart \ -DarchetypeVersion=1.4 \ -DinteractiveMode=false - In informattooutformat/pom.xml:
- set the artifactId as "informat-to-outformat"
- prefix the name with "nzilbb.converter."
- change version to "0.1.0" - i.e. use semantic versioning.
- remove the url tag (so it can be inherited from the master pom.xml)
- add a description tag
- change maven.compiler.source and maven.compiler.target to "1.8"
- add the following to properties
<input.package>nzilbb.formatter.informattool</input.package> <input.path>nzilbb/formatter/informattool/</input.path> <input.version>i.i.i</input.version> <output.package>nzilbb.formatter.outformattool</output.package> <output.path>nzilbb/formatter/outformattool/</output.path> <output.version>o.o.o</output.version>- add the following to dependencies
<dependency> <groupId>nz.ilbb.ag</groupId> <artifactId>${input.package}</artifactId> <version>[${input.version},)</version> </dependency> <dependency> <groupId>nz.ilbb.ag</groupId> <artifactId>${output.package}</artifactId> <version>[${output.version},)</version> </dependency> <dependency> <groupId>nz.ilbb.ag</groupId> <artifactId>nzilbb.ag</artifactId> <version>1.4.1</version> </dependency>- add the following to build
<plugins> <plugin> <groupId>org.codehaus.mojo</groupId> <artifactId>exec-maven-plugin</artifactId> <version>3.5.1</version> <executions> <execution> <phase>pre-site</phase> <goals> <goal>java</goal> </goals> </execution> </executions> <configuration> <mainClass>nzilbb.converter.InputFormatToOutputFormat</mainClass> <arguments> <argument>--helpmarkdown=${project.basedir}/src/site/markdown/index.md</argument> </arguments> <blockSystemExit>true</blockSystemExit> </configuration> </plugin> <plugin> <artifactId>maven-jar-plugin</artifactId> <version>3.0.2</version> <configuration> <archive> <manifest> <mainClass>nzilbb.converter.InformatToOutformat</mainClass> </manifest> <!-- ensure version is available to the serializations --> <manifestSections> <manifestSection> <name>nzilbb/converter/</name> <manifestEntries> <Implementation-Title>${project.description}</Implementation-Title> <Implementation-Version>${project.version}</Implementation-Version> <Implementation-Vendor>New Zealand Institute of Language, Brain and Behaviour</Implementation-Vendor> </manifestEntries> </manifestSection> <manifestSection> <name>${input.path}</name> <manifestEntries> <Implementation-Title>${project.description}</Implementation-Title> <Implementation-Version>${input.version}</Implementation-Version> <Implementation-Vendor>New Zealand Institute of Language, Brain and Behaviour</Implementation-Vendor> </manifestEntries> </manifestSection> <manifestSection> <name>${output.path}</name> <manifestEntries> <Implementation-Title>${project.description}</Implementation-Title> <Implementation-Version>${output.version}</Implementation-Version> <Implementation-Vendor>New Zealand Institute of Language, Brain and Behaviour</Implementation-Vendor> </manifestEntries> </manifestSection> </manifestSections> </archive> <outputDirectory>../bin</outputDirectory> </configuration> </plugin> <!-- include all the necessary dependencies in our jar for it to run standalone --> <plugin> <groupId>org.apache.maven.plugins</groupId> <artifactId>maven-dependency-plugin</artifactId> <executions> <execution> <id>unpack</id> <phase>generate-sources</phase> <goals> <goal>unpack</goal> </goals> <configuration> <artifactItems> <artifactItem> <groupId>nz.ilbb.ag</groupId> <artifactId>${input.package}</artifactId> <version>${input.version}</version> <outputDirectory>${project.build.directory}/classes</outputDirectory> </artifactItem> <artifactItem> <groupId>nz.ilbb.ag</groupId> <artifactId>${output.package}</artifactId> <version>${output.version}</version> <outputDirectory>${project.build.directory}/classes</outputDirectory> </artifactItem> <artifactItem> <groupId>nz.ilbb.ag</groupId> <artifactId>nzilbb.ag</artifactId> <version>1.3.0</version> <outputDirectory>${project.build.directory}/classes</outputDirectory> </artifactItem> <artifactItem> <groupId>org.glassfish</groupId> <artifactId>javax.json</artifactId> <version>1.1.4</version> <outputDirectory>${project.build.directory}/classes</outputDirectory> </artifactItem> </artifactItems> </configuration> </execution> </executions> </plugin> </plugins> - Remove the groupId-based source code structure:
cd informattooutformat rm -r src/main/java/nz src/test/java/nz - Add directory structure for the converter code:
mkdir src/main/java/nzilbb src/main/java/nzilbb/converter src/main/resources \ src/main/resources/nzilbb src/main/resources/nzilbb/converter \ src/test/java/nzilbb \ src/test/java/nzilbb/converter src/test/resources src/test/resources/nzilbb \ src/test/resources/nzilbb/converter src/site/ \ src/main/resources/nzilbb/converter src/main/resources/nzilbb/converter/images - Add an icon for the converter, e.g.:
cp ../../ag/src/site/resources/images/labbcat.png \ src/main/resources/nzilbb/converter/InformatToOutformat.pngo - Add your implementation to\ informattooutformat/src/main/java/nzilbb/converter/InformatToOutformat.java