
Tests that call real LLM APIs are slow, cost money, and give different answers each run.
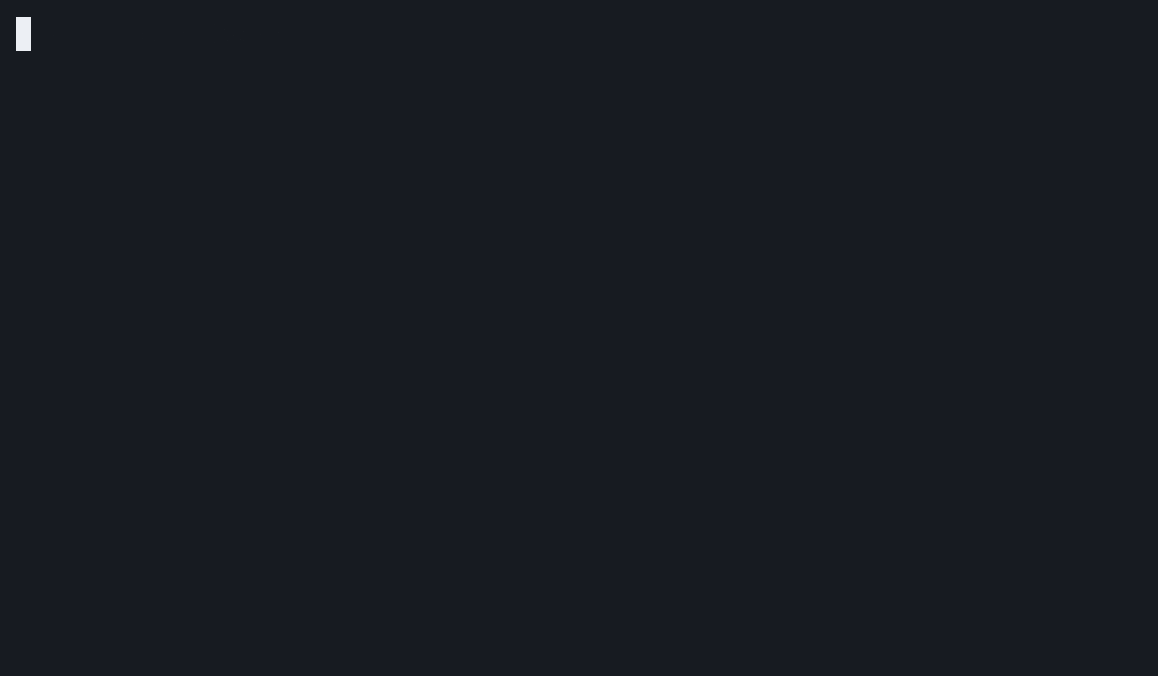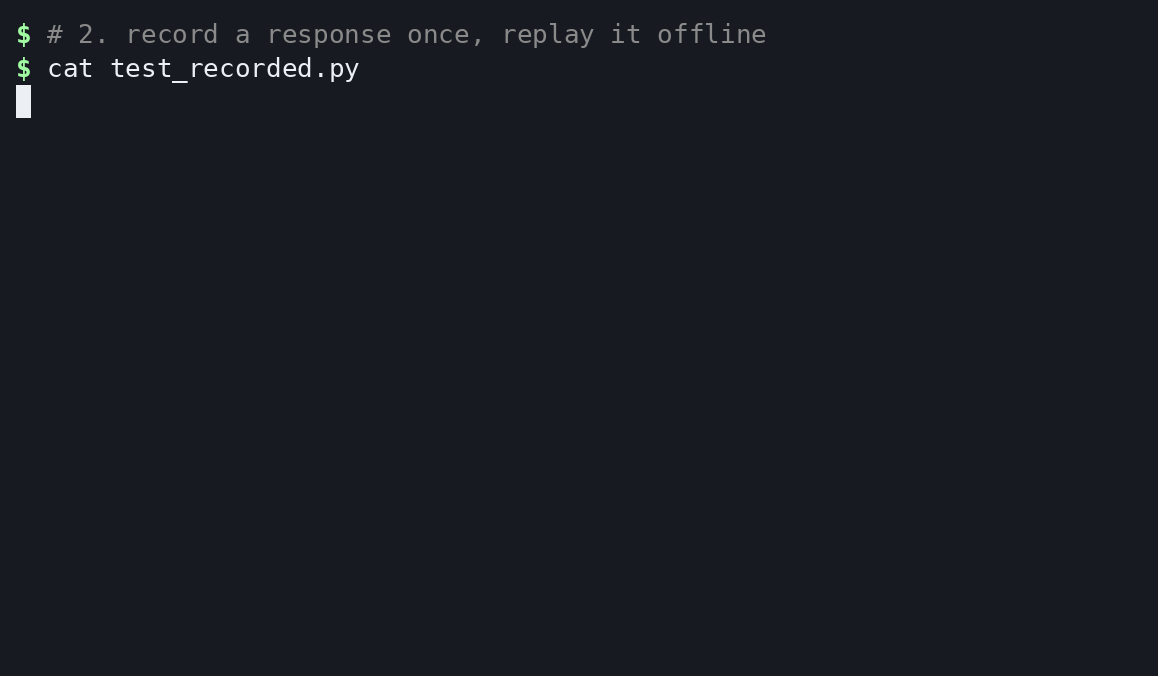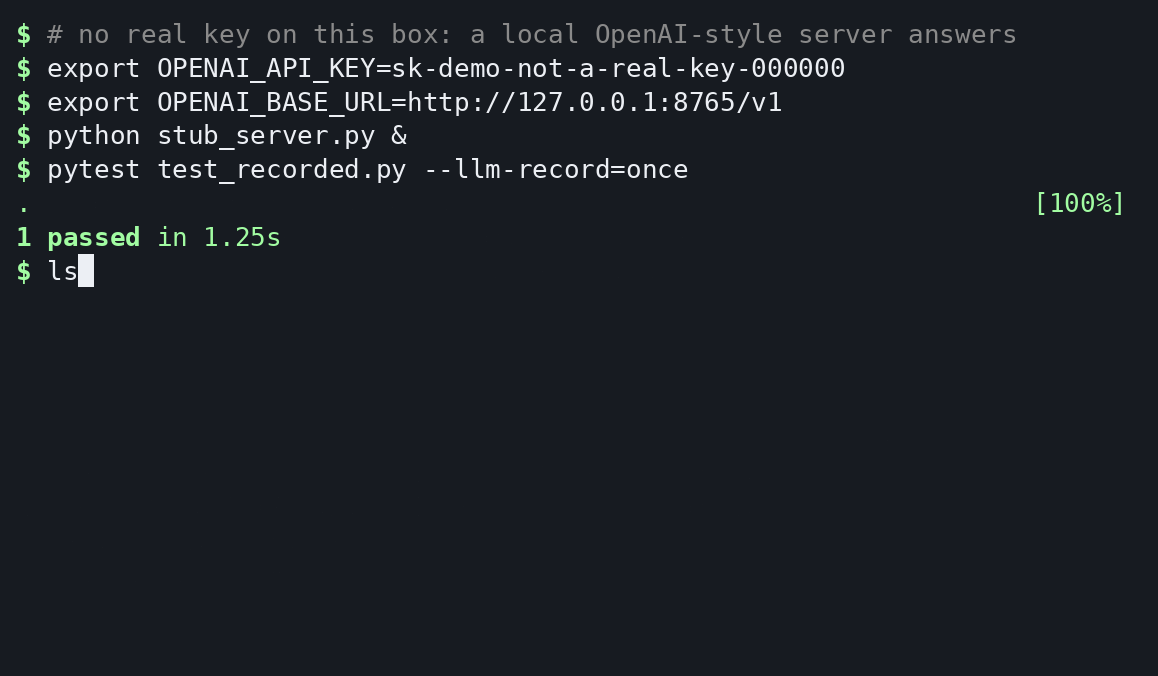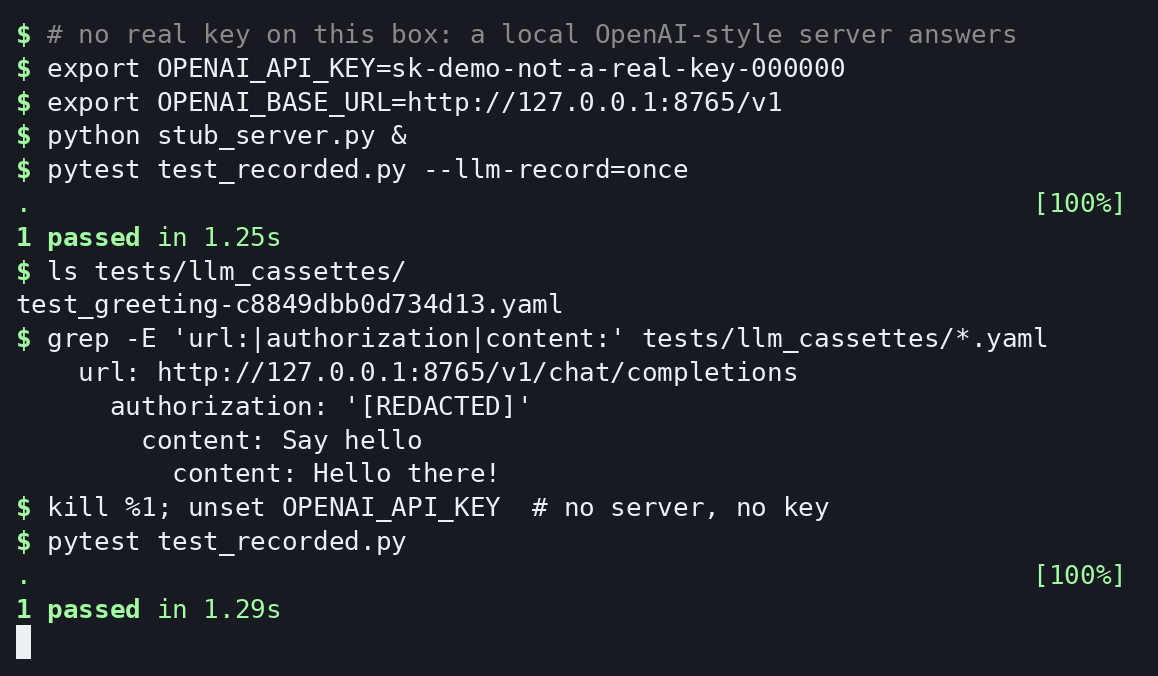
In the recording part of the demo, a local OpenAI-compatible server stands in for the API because the demo machine has no real key.
Configure the answer, run your Python code, and assert what it sent to the model. Auto-discovered pytest fixtures for OpenAI, Anthropic, Google Gemini, and LangChain. MIT licensed. No API key is needed for mocked tests.
pip install "pytest-mockllm[openai]"Save this as test_chat.py, then run pytest:
from openai import OpenAI


def test_chat(mock_openai):
    mock_openai.add_response("Hello, Ada!")
    with OpenAI(api_key="fixture-only") as client:
        reply = client.chat.completions.create(
            model="gpt-4o-mini",
            messages=[{"role": "user", "content": "My name is Ada"}],
        )
    assert reply.choices[0].message.content == "Hello, Ada!"
    assert mock_openai.call_count == 1
    assert mock_openai.last_call["model"] == "gpt-4o-mini"
    assert "Ada" in mock_openai.last_call["messages"][0]["content"]
In your application tests, call your own function in place of the SDK call above.
The fixture intercepts supported SDK calls, including clients imported or created
before the fixture starts. No fixture imports or pytest_plugins setting are needed.
The placeholder key satisfies SDK construction; it is never sent by the mock.
Install only what you use: [openai], [anthropic], [google], or [langchain].
[all] installs the current integrations; the base package does not install provider SDKs.
| Fixture | Supported interfaces |
|---|---|
mock_openai |
Chat Completions, Responses create/parse, embeddings; sync/async; text and function-call streams |
mock_anthropic |
Messages create/stream; sync/async; text and tool-use streams |
mock_gemini |
google.genai.Client models generate_content/generate_content_stream, chat sessions; sync/async |
mock_langchain |
ChatOpenAI-compatible invoke/ainvoke, stream/astream, structured output; direct mock_langchain.model |
mock_llm |
OpenAI by default; select a provider with @pytest.mark.llm_mock(provider="anthropic") |
These are scoped test doubles, not complete emulators. Installing the plugin alone blocks no traffic. Active OpenAI, Anthropic, and modern Gemini mocks reject unhandled HTTP SDK requests. Realtime/WebSocket APIs, file uploads, and arbitrary network traffic are outside this guarantee. LangChain and legacy Gemini intercept their documented methods only. SDK constructor validation still applies.
from openai import OpenAI
from pydantic import BaseModel


class Contact(BaseModel):
    name: str


def test_responses(mock_openai):
    mock_openai.add_response('{"name":"Ada"}')
    with OpenAI(api_key="fixture-only") as client:
        result = client.responses.parse(
            model="gpt-4o-mini", input="Extract Ada's name", text_format=Contact,
        )
assert result.output_parsed == Contact(name="Ada")from anthropic import Anthropic
def test_claude(mock_anthropic):
mock_anthropic.add_response("Your order is on its way.")
with Anthropic(api_key="fixture-only") as client:
reply = client.messages.create(
model="claude-sonnet-4-5", max_tokens=100,
messages=[{"role": "user", "content": "Where is my order?"}],
)
assert reply.content[0].text == "Your order is on its way."The [google] extra uses google-genai, not the retired google-generativeai SDK.
For a migration period, [google-legacy] also installs the old SDK; its existing
GenerativeModel adapter remains available with a deprecation warning.
from google import genai


def test_gemini(mock_gemini):
    mock_gemini.add_response("Paris")
    with genai.Client(api_key="fixture-only") as client:
        reply = client.models.generate_content(
            model="gemini-2.5-flash", contents="Capital of France?",
        )
    assert reply.text == "Paris"
assert mock_gemini.last_call["contents"] == "Capital of France?"client.chats.create(...).send_message(...), client.aio.models.generate_content(...),
and await client.aio.models.generate_content_stream(...) use the same response queue.
Generated responses expose SDK candidates, function_calls, and usage_metadata.
from langchain_core.prompts import ChatPromptTemplate
from langchain_openai import ChatOpenAI


def test_chain(mock_langchain):
    mock_langchain.add_response("Paris")
    prompt = ChatPromptTemplate.from_template("Capital of {country}?")
    model = ChatOpenAI(model="gpt-4o-mini", api_key="fixture-only")
    assert (prompt | model).invoke({"country": "France"}).content == "Paris"
This replaces the model call, so it does not exercise LangChain's provider transport, callbacks, or automatic tool execution. Tool responses do not execute your Python tools.
import pytest
from openai import AsyncOpenAI, OpenAI


@pytest.mark.asyncio
async def test_async(mock_openai):
    mock_openai.add_response("Async answer")
    async with AsyncOpenAI(api_key="fixture-only") as client:
        reply = await client.chat.completions.create(model="gpt-4o-mini", messages=[])
    assert reply.choices[0].message.content == "Async answer"


def test_stream(mock_openai):
    mock_openai.add_response("Hello world", stream_chunks=["Hello ", "world"])
    with OpenAI(api_key="fixture-only") as client:
        stream = client.chat.completions.create(
            model="gpt-4o-mini", messages=[], stream=True,
        )
        text = "".join(chunk.choices[0].delta.content or "" for chunk in stream)
    assert text == "Hello world"
Anthropic messages.create(stream=True) yields official SDK events, including
content_block_delta. Use tool_call_chunks for fragmented JSON arguments in OpenAI
chat and Anthropic tool streams. Both provider mocks and record/replay support SDK stream context managers.
OpenAI Responses streams also support get_final_response() and structured parsing.
import json
from openai import OpenAI


def test_tool_call(mock_openai):
    mock_openai.add_response("", tool_calls=[{
        "id": "call_weather",
        "function": {"name": "weather", "arguments": {"city": "Paris"}},
    }])
    with OpenAI(api_key="fixture-only") as client:
        reply = client.chat.completions.create(model="gpt-4o-mini", messages=[])
    tool = reply.choices[0].message.tool_calls[0]
    assert tool.function.name == "weather"
    assert json.loads(tool.function.arguments) == {"city": "Paris"}
The same tool_calls configuration produces Anthropic tool_use blocks and Gemini
function-call parts. Configure what the model returns, then test whether your application
validates the arguments and invokes the right tool.
import pytest
from openai import OpenAI, RateLimitError


def test_retry_logic(mock_openai):
    mock_openai.simulate_error("rate_limit", times=1)
    mock_openai.add_response("Recovered")
    with OpenAI(api_key="fixture-only") as client:
        with pytest.raises(RateLimitError):
            client.chat.completions.create(model="gpt-4o-mini", messages=[])
        reply = client.chat.completions.create(model="gpt-4o-mini", messages=[])
    assert reply.choices[0].message.content == "Recovered"
    assert [call["outcome"] for call in mock_openai.request_ledger] == ["rate_limit", "success"]
Mock errors occur at the SDK method boundary: use them to test your application's
retry handling. To exercise the SDK's internal HTTP retry loop, use record/replay.
Supported errors include rate_limit, auth, timeout, server, and invalid_request;
Anthropic also supports overloaded. after_calls=N delays an error until N successes.
times=N bounds it. call_count counts successful configured responses; calls and
request_ledger include failed attempts.
Use add_responses("first", "second") to queue answers. After the queue is exhausted,
set_default_response(...) supplies a fallback; otherwise non-strict mode returns a
placeholder answer. Strict mode catches missing responses:
pytest --llm-strictOr call mock_openai.set_strict_mode() in one test. Token usage is configurable with
TokenUsage; cost estimates use a static price table and are not billing measurements.
Token counting uses preloaded tiktoken encoders when available, otherwise a character
estimate. It never downloads tokenizers implicitly; preload an encoder explicitly if
you need exact tokenization, or supply TokenUsage for deterministic budget tests.
Use llm_recorder instead of a provider mock fixture. It captures OpenAI Chat
Completions, Responses (including structured parsing), embeddings, and Anthropic Messages.
The SDK parses the recorded HTTP JSON or SSE into its normal response objects.
import os
from openai import OpenAI


def test_recorded_reply(llm_recorder):
    with OpenAI(api_key=os.getenv("OPENAI_API_KEY", "replay-only")) as client:
        reply = client.responses.create(model="gpt-4o-mini", input="Say hello.")
    assert reply.output_text
Set your provider key in the environment for the first run:
pytest test_recorded.py --llm-record=once  # real API calls if no cassette exists
pytest test_recorded.py # offline replay; no key needed| Mode | Existing matching interaction | Missing/exhausted interaction |
|---|---|---|
none (default) |
Replay | Fail without sending HTTP |
once |
Replay | Record only if the cassette file did not exist on entry |
new_episodes |
Replay | Record and append |
all |
Record again | Record; replace the old cassette |
Bare --llm-record means all for compatibility. Live modes make billable API calls.
The flag affects tests using llm_recorder or the markers; it does not activate recording
across your entire suite. @pytest.mark.llm_record activates the fixture, with offline
defaults. @pytest.mark.llm_record(mode="once") selects a mode for one test.
@pytest.mark.llm_replay forces offline replay even when the CLI requests recording.
Cassettes live under tests/llm_cassettes/, relative to pytest's root directory. Names
include a hash of the full test ID, including module, class, and parameters. Override
with --llm-cassette-dir=... or llm_cassette_dir. Review and commit cassettes for CI;
the repository's own local cassette directory is ignored by Git.
Matching includes provider, HTTP method, URL/query, JSON request body (including model, prompt, tools, sampling parameters, and stream flag), and selected API-version/project headers. Credential and SDK telemetry headers do not affect matching. Identical requests consume recorded responses in order; a cassette cannot be replayed infinitely in one test. Changing the base URL or a prompt requires a matching recording.
Credential headers and query parameters, known key/token patterns, and credentials used
by the SDK are redacted, including echoes in JSON or SSE. JSON fields named key, token,
or auth are preserved unless their values contain a recognized secret. This is not general
PII removal: prompts and model output remain readable. Review cassettes before committing.
Redacted fields replay as redacted values.
Recording buffers the complete response, including streams, before handing it to the SDK;
replay preserves SSE events and tool fragments, not network timing. Incomplete HTTP reads
are not saved. Completed interactions are saved atomically even if a later test assertion
fails. OpenAI/Anthropic HTTPX and HTTPX2 clients are covered; custom clients that override
send are rejected (use a custom transport instead). WebSockets, non-JSON requests,
other SDK endpoints, Gemini recording, overlapping recorder contexts, and concurrent
writers to the same cassette file are not supported. Separate tests get separate files.
For direct context-manager use, choose LLMRecorder(path, record_mode="once").
Legacy mode="auto", "record", and "replay" map to once/all/none with a deprecation
warning. Legacy mode="none" still means explicit live pass-through; migrate to
record_mode="none" for offline replay.
| Tool | Choose it when | Where pytest-mockllm fits |
|---|---|---|
| unittest.mock | You want general-purpose patching, specs, and call assertions with no extra dependency. | Queues, provider-shaped responses, streams, and errors require less setup here; mock gives more control. |
| respx | You want precise HTTPX route matching and transport-level assertions. | Provider fixtures avoid constructing HTTP payloads. Use a transport tool when wire behavior is the subject of your test. |
| vcrpy | You need mature HTTP recording across multiple services and client libraries. | Our narrower recorder targets OpenAI/Anthropic JSON and SSE; vcrpy has a broader ecosystem and configuration surface. |
| pytest-recording | You want pytest integration for VCR.py, cassette markers, and network controls. | This plugin combines handwritten LLM responses and scoped LLM cassettes. Keep pytest-recording for general HTTP integration tests. |
| deepeval / promptfoo | You need to evaluate answer quality, prompt changes, or model behavior. | Those judge generated answers; this plugin tests the code around the model. Use both when you need both kinds of evidence. |
A passing mocked test does not prove a prompt produces a good answer or that the live service accepts your request. Keep a small live integration suite and separate evaluations.
[tool.pytest.ini_options]
llm_strict = true
llm_stats = false
llm_cassette_dir = "tests/llm_cassettes"
Statistics are off by default. Enable with pytest --llm-stats or llm_stats = true;
--no-llm-stats overrides both. There is no cost banner in a normal run.
Demo tests run offline. See the recorded run, or generate an asciinema v2 recording of
an actual run with python scripts/record_demo.py; play it with asciinema play docs/demo.cast.
The script needs only the [openai] extra and does not fabricate test output.
pip install -e ".[all,dev]" build
pytest
ruff check src/
mypy src/
python -m build
See CONTRIBUTING.md, CHANGELOG.md, and the SDK compatibility notes for tested versions and limits.
MIT licensed — LICENSE. Maintained by Dhiraj Das.