



I build tools that turn hard-to-debug failures into reproducible, inspectable evidence.
把难以定位的问题,变成更小的复现案例、可执行测试与可审查的证据。
Selected work · Research · Upstream contributions · Engineering approach · All repositories


Three open-source tools, connected by one idea: make a failure concrete enough to reproduce, inspect, and fix. These are early-stage tools with documented boundaries, not claims of production maturity or general model accuracy.
Reduce a failing browser journey to a verified reproducer and a runnable regression test.
ReproCut runs deletion experiments in fresh Chromium contexts and keeps a shorter action sequence only when the same declared failure still reproduces. It exports a replayable journey, a Playwright regression test, an offline evidence report, and a repair brief for a developer or coding agent.
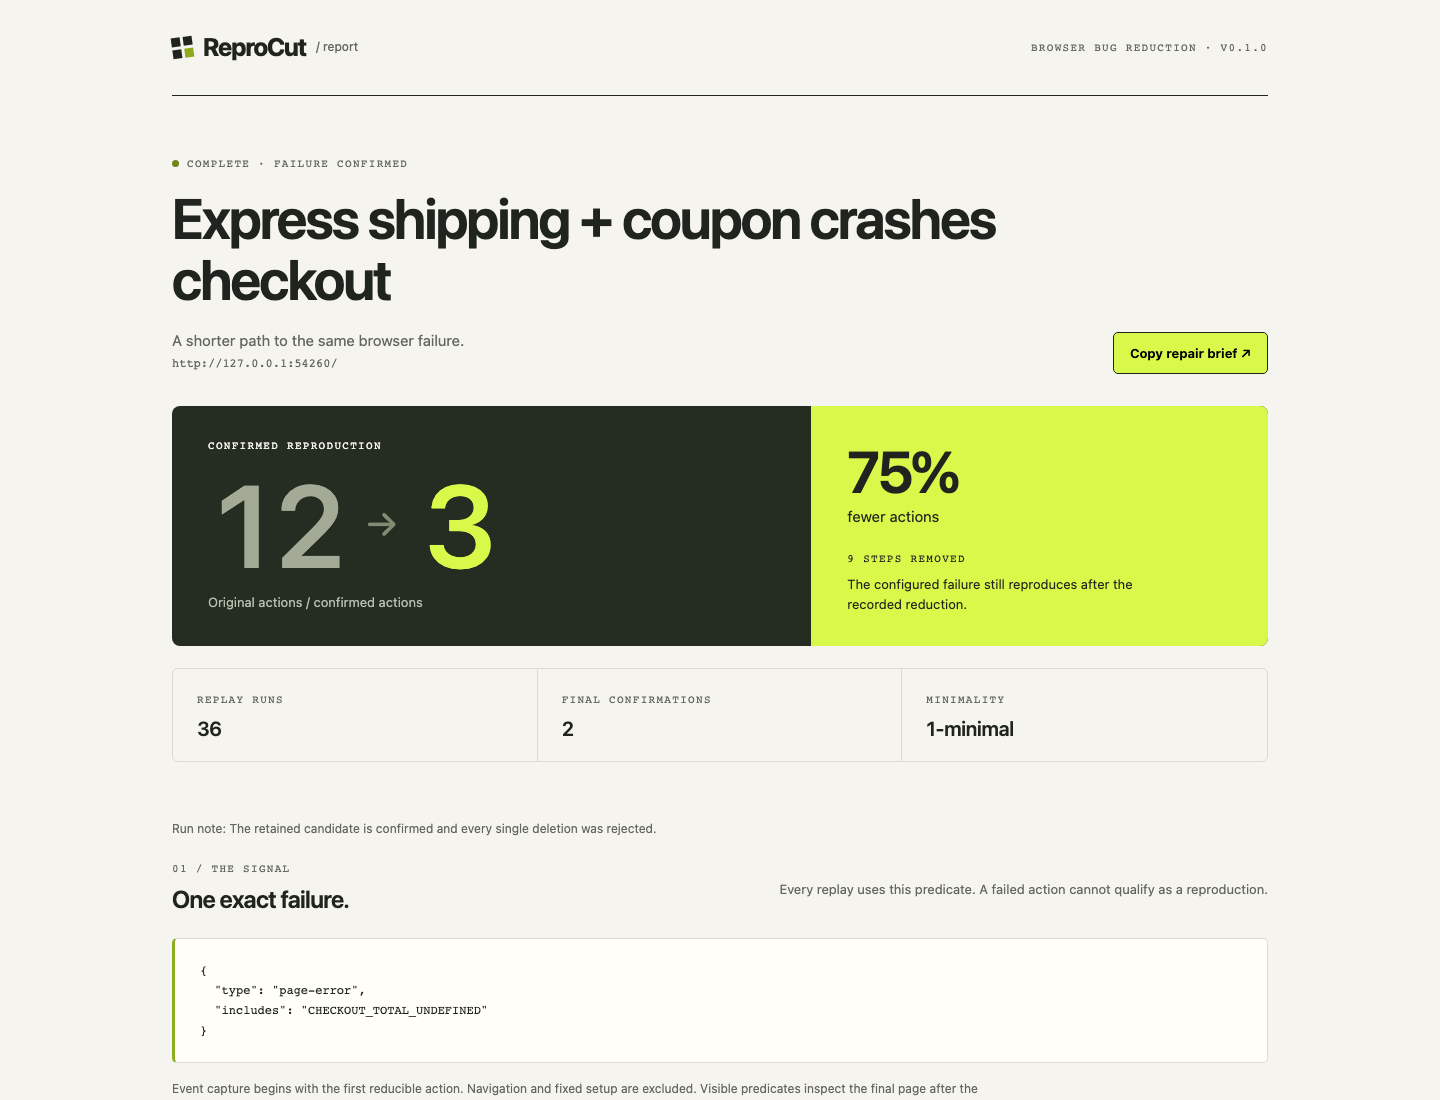
Recorded demo: 12 → 3 actions · 36 browser replays · 75% fewer steps. One deterministic fixture, not a cross-application benchmark. Verified reductions are single-deletion minimal under the observed replay conditions, not guaranteed globally shortest.
JavaScript Node.js Playwright Delta debugging
Source & quick start · Demo artifacts & releases · 中文介绍
02 / RenderWitnessVisual regression review, backed by inspectable evidence. 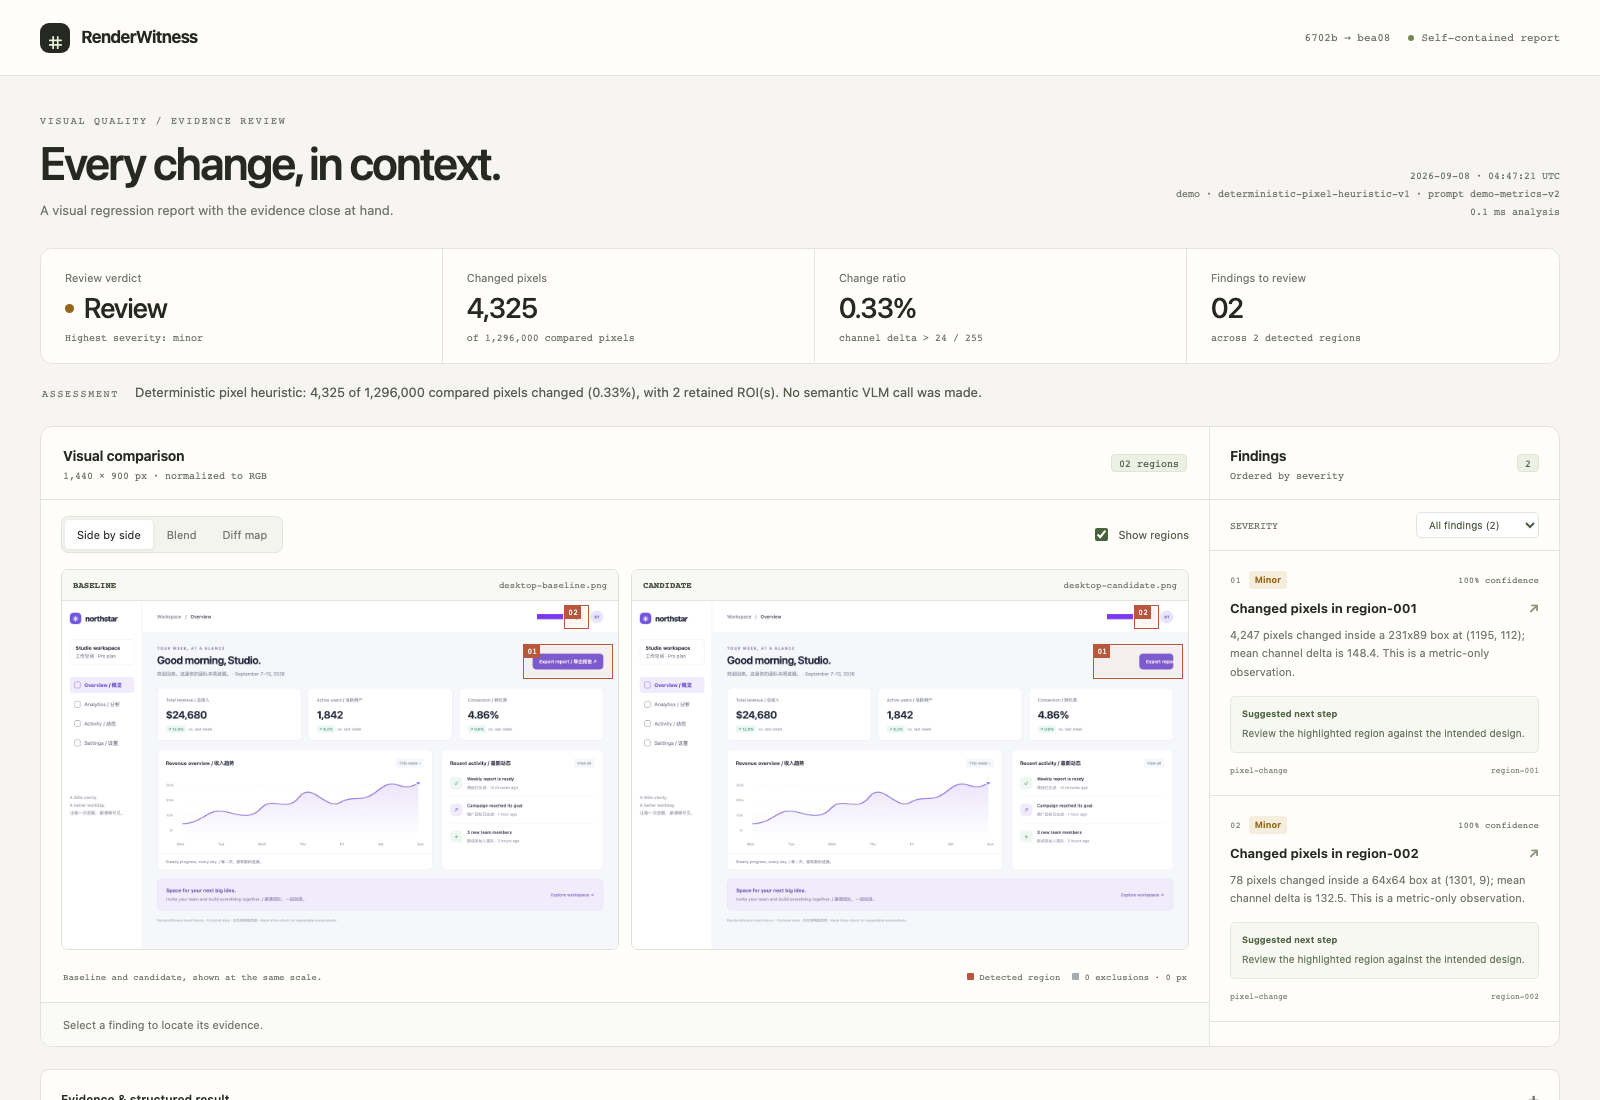
Capture browser screenshots, isolate changed regions, and review the result with side-by-side, blend, and diff views. Includes scenario suites, ignore regions, explicit CI gates, and HTML / JSON / Markdown / JUnit exports. Optional VLM analysis stays separate from deterministic pixel evidence. The illustrated demo is metric-only; it does not establish real-VLM accuracy. Alpha tool.
Source & demo · CI guide · 中文 |
03 / DreamFuzzFind, shrink, and replay world-model failures. 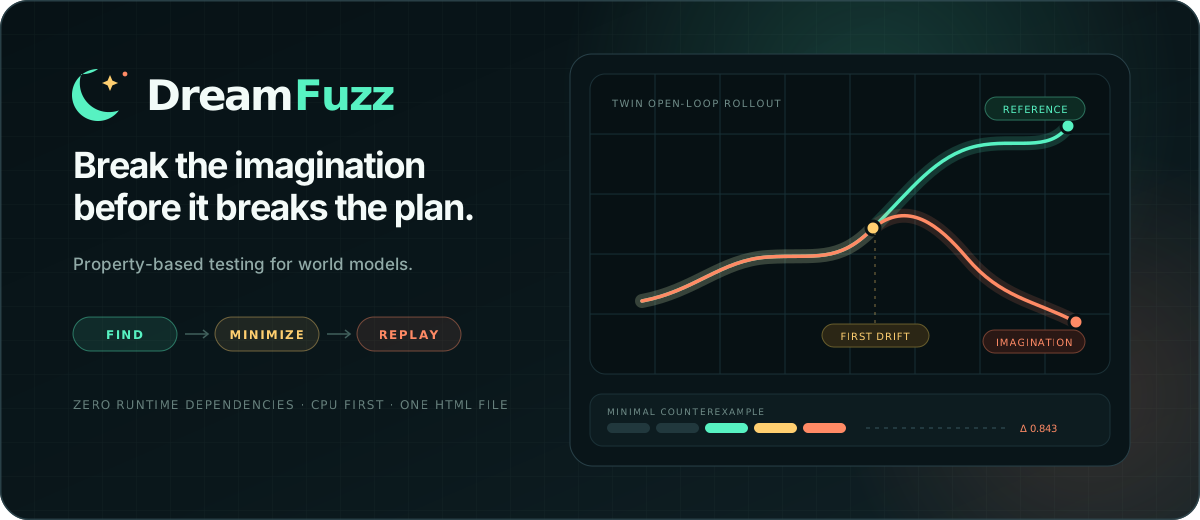
Search for action sequences that expose model-vs-reference rollout drift, minimize the counterexample, and export a self-contained HTML replay. Uses explicit behavioral properties, paired open-loop rollouts, reproducible seeds, and an adapter contract for custom targets. The core has no third-party runtime dependencies. Alpha diagnostic tool, not a model-training framework or a general evaluation leaderboard.
Source · Live replay · 中文 |
I am interested in reliable multimodal systems, long-video understanding, and learning from limited supervision. My focus is on making model behavior testable, evidence traceable, and evaluation reproducible.
Public software is listed above. Research manuscripts, results, and code are linked only when cleared for public release.
I also work on focused bug fixes, regression tests, documentation, and code review in existing projects. Original projects, submitted patches, and review contributions are listed separately.
| Project | Contribution | Evidence |
|---|---|---|
| Podman Desktop | Fixed navigation resize-handle layering beneath the welcome overlay, with a Playwright hit-test regression. | Merged PR #18998 |
| Project | Contribution | Evidence |
|---|---|---|
| Instructor | Preserve GenAI text-part metadata during templating, including thought signatures, without mutating caller-owned content. | PR #2608 |
| Stable World Model | Fix single-step iCEM planning so the existing horizon-one sampling path runs without an index error. | PR #323 |
| OpenPI | Preserve histogram counts when normalization ranges expand, with regression coverage for quantile estimates. | PR #1041 |
| tqdm | Fix notebook progress bars with CSS widths while preserving widget layout and numeric-width behavior. | PR #1823 |
| LiteLLM | Preserve caller-provided spend metadata on authentication failures, with safe parsing and regression coverage. | PR #38493 |
| MuJoCo | Clarify regularized-friction creep, the limits of impratio, and NoSlip tradeoffs in the documentation. |
PR #3526 |
Status checked on September 8, 2026: the six PRs above were open. The linked upstream threads are the source of truth for later changes.
LeRobot: reviewed the intermediate-prediction contract for world-model policies and reported regression risks around evaluation flag propagation and non-image outputs entering the video path. Review on PR #3757.
| Principle | What it looks like in the work |
|---|---|
| A concrete failure before a broad claim | A smaller browser journey, a model counterexample, or a numbered visual region—not just an aggregate score. |
| Evidence separate from interpretation | Deterministic measurements and replay artifacts remain inspectable; model recommendations carry explicit limits. |
| Regression coverage with the fix | Focused tests document the failure mode and guard the behavior being changed. |
| Useful handoffs | Runnable tests, structured JSON, portable reports, and documentation that another developer can use. |


Jason Hu
AI reliability · World models · Multimodal systems · Open source