
In-flight circuit breaker & reasoning loop recovery for LangGraph & LangChain agents





⚡ Quick Start · 📖 Documentation · ⚙️ API Reference · 🔍 Loop Detection · 📜 Changelog
"Why did my agent just burn $14 repeating the exact same search 20 times?" — now you have an in-flight circuit breaker that detects loops and recovers gracefully.
When autonomous LLM agents hit an unexpected hurdle, they often get trapped in repetitive reasoning loops: calling identical tools with the same parameters, oscillating between two conflicting thoughts, or drifting aimlessly while burning thousands of tokens.
LangGraph's built-in recursion_limit is a hard crash (GraphRecursionError). It drops state, discards user context, and provides zero opportunity for recovery.
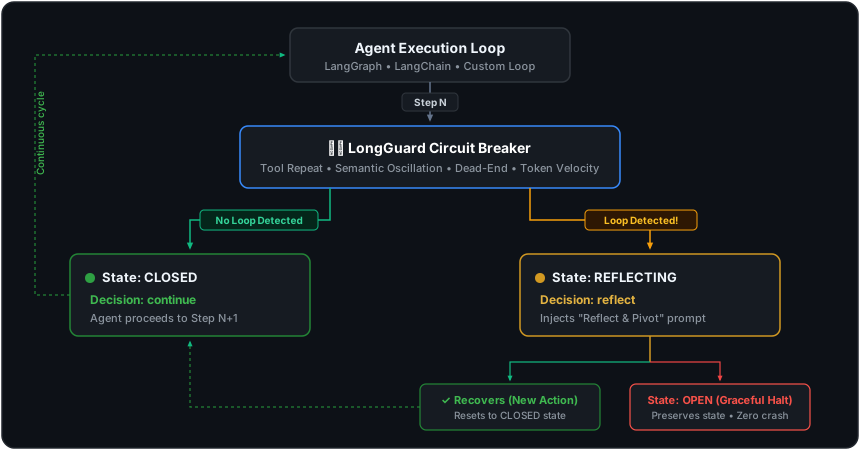
LongGuard is an intelligent circuit breaker middleware. It monitors your agent's chain-of-thought in real time, catches loops early, injects a "Reflect & Pivot" prompt to guide the agent back on track, and only halts (kill) gracefully if recovery fails—preserving complete state and token analytics.
- ⚡ Measured Sub-millisecond Overhead: Median ~350 µs per step across all 4 default detectors combined (p95 < 850 µs with lightweight hash embeddings). Runs in-process without slowing down LLM inference. See Performance & Overhead.
- 🔄 4 loop detectors: Catches tool repetition, semantic oscillation, dead-end drift, and token velocity spikes.
- 🧭 Reflect & Pivot prompt injection: Guides stuck agents back on track before giving up.
- 🛡️ Zero unhandled crashes: Gracefully terminates and preserves conversation state if recovery fails.
- 🔌 1-line framework integrations: Drop-in wrapper for LangGraph 1.0+ (
add_guard_to_graph), LangChain (GuardedAgentExecutor), and CrewAI (add_guard_to_crew). - 🔁 Safe LangGraph resume: Explicitly continue an eligible stopped graph run via
compile_guarded_graph&GuardedGraph.resumewithout replaying completed tool calls. - 🧹 Tool-call history cleanup: Original-ID cleanup for LangChain, OpenAI, and Anthropic histories keeps the conversation protocol-consistent after a trip.
- 🪄 Universal
@guardeddecorator: 1-line protection for arbitrary Python functions, generators, and async loops. - 🐍 Raw client support: Use LongGuard directly with
openaioranthropicSDK — no framework needed. - 💵 Dollar cost tracking: Built-in model pricing; use
list_supported_models()to see the current registry. Setmax_cost_usdto hard-kill on budget overrun. - 📊 Full observability: Detailed
GuardReportwith per-step telemetry. Save to JSON/YAML. Load for offline analysis.
# Core package (standalone, zero heavy dependencies)
pip install longguard

# With LangGraph integration (LangGraph 1.0+)
pip install longguard[langgraph]

# With LangChain integration
pip install longguard[langchain]

# With CrewAI integration
pip install longguard[crewai]

# With high-quality sentence embeddings
pip install longguard[embeddings]

# Everything
pip install longguard[all]
Python 3.11 – 3.13 tested and supported on Linux, macOS, and Windows.
Lightweight by default: LongGuard evaluates loops out of the box with zero heavy ML dependencies usingHashBasedEmbedder(~350 µs median per step). For high-dimensional neural representations, installpip install longguard[embeddings].
Compatible with LangGraph 1.0+ and modern multimodal models (Claude 3.7, Gemini 2.5, GPT-4o):
from langgraph.graph import StateGraph
from longguard.integrations.langgraph import add_guard_to_graph
from longguard import GuardConfig

# 1. Build your LangGraph workflow as usual
workflow = StateGraph(AgentState)
workflow.add_node("agent", agent_node)
workflow.add_node("tools", tool_node)
workflow.add_edge("agent", "tools")
workflow.add_conditional_edges("tools", should_continue)

# 2. Add LongGuard in one line!
workflow = add_guard_to_graph(workflow, GuardConfig())
app = workflow.compile()

# 3. Read execution telemetry after run
guard = workflow.__longguard__
print(guard.get_report().summary())Continue an eligible stopped run without replaying completed tool calls. State, tool-call IDs, and token accounting are all preserved:
from langgraph.checkpoint.memory import MemorySaver
from longguard import GuardConfig
from longguard.integrations.langgraph import compile_guarded_graph

checkpointer = MemorySaver()

# compile_guarded_graph wraps your workflow and injects interrupts at node boundaries
guarded_graph = compile_guarded_graph(workflow, GuardConfig(), checkpointer=checkpointer)

# First invocation
result = guarded_graph.invoke({"messages": [...]}, config={"configurable": {"thread_id": "t1"}})

# Explicit, controlled resume — only valid after an eligible stopped checkpoint
result = guarded_graph.resume("t1")

# Each run gets an independent report
print(guarded_graph.report("t1").summary())Protect multi-agent crews from delegation loops and repetitive tool calls:
from crewai import Crew
from longguard import GuardConfig
from longguard.integrations.crewai import add_guard_to_crew

crew = Crew(agents=[researcher, writer], tasks=[task1, task2])
crew = add_guard_to_crew(crew, GuardConfig(model="gpt-4o", max_cost_usd=1.00))
result = crew.kickoff()

print(crew.__longguard__.summary())
Note: CrewAI support is explicitly bounded to the tested sequential ReAct executor. Unsupported execution modes fail clearly; callback-only
CrewGuardremains available for other topologies.
Add circuit breaking to any custom agent function or LLM call:
from longguard import guarded

@guarded(max_cost_usd=0.50, tool_repeat_threshold=3)
def run_agent_step(thought: str, action: str, action_input: dict, observation: str):
    return execute_tool(action, action_input)

# Check execution report at any time:
print(run_agent_step.report.summary())Call LongGuard directly from any while loop — works with plain openai or anthropic SDK:
import openai
from longguard import AgentStep, CircuitBreaker, GuardConfig

client = openai.OpenAI()
breaker = CircuitBreaker(GuardConfig(
    model="gpt-4o",        # enables dollar-cost tracking
    max_cost_usd=0.50,     # hard-kill if run exceeds $0.50
    max_steps=30,
))

observation = None
for i in range(1, 31):
    response = client.chat.completions.create(model="gpt-4o", messages=messages)

    # One-line conversion from SDK response → AgentStep
    step = AgentStep.from_openai_response(response, step_number=i, observation=observation)
    decision = breaker.check(step)

    if decision.action == "kill":
        print(f"⛔ Halted: {decision.reason}")
        break
    elif decision.action == "reflect":
        messages.append({"role": "system", "content": decision.inject_prompt})

    if step.action is None:
        break  # final answer
    observation = run_tool(step.action, step.action_input)

# Full run report including estimated cost
print(breaker.report.summary())
# → Estimated Cost: $0.0143 USD (gpt-4o)
For Anthropic: use
AgentStep.from_anthropic_response(response, step_number=i)— same API, zero dependencies.
If you run a custom while loop or proprietary agent orchestrator:
from longguard import CircuitBreaker, GuardConfig, AgentStep

breaker = CircuitBreaker(GuardConfig(
    tool_repeat_threshold=3,    # 3 identical tool calls = trigger
    max_tokens_per_run=50_000,  # Hard token cap
))

for step in run_agent():
    decision = breaker.check(AgentStep(
        step_number=step.index,
        thought=step.thought,
        action=step.tool_name,
        action_input=step.arguments,
        observation=step.tool_output,
        tokens_used=step.tokens,
    ))

    if decision.action == "reflect":
        # Inject the recovery advice into your agent's context
        messages.append({"role": "user", "content": decision.inject_prompt})
    elif decision.action == "kill":
        print(f"Halted safely: {decision.reason}")
        break

# View summary report
print(breaker.report.summary())| Detector | What It Catches | Real-World Example |
|---|---|---|
| 🔄 Tool Repeat | Calling the same tool with identical inputs |
Agent calls search("revenue 2025") 4 times with zero parameter changes |
| 🌀 Semantic Oscillation | Cycling between the same concepts in reasoning | Agent reasons "Option A", then "No, B", then "Actually A", then "No, B" |
| 📉 Dead-End Drift | Zero new information or observations for 5+ steps | Queries return empty results or repetitive error strings |
| ⚡ Token Velocity | Sudden exponential token spikes per step | Agent injects giant raw HTML payloads into context, blowing budget |
| Capability | LangGraph recursion_limit |
LongGuard 🛡️ |
|---|---|---|
| Detects Tool-Repeat Loops | ❌ No | ✅ Yes |
| Detects Semantic Reasoning Loops | ❌ No | ✅ Yes |
| Detects Sudden Cost / Token Spikes | ❌ No | ✅ Yes |
| Auto-Injects Recovery Prompts | ❌ No | ✅ Yes |
| Safe Graph Resume (no tool replay) | ❌ No | ✅ Yes (sync, same-process) |
| Exit Behavior | 💥 Unhandled Exception (Crash) |
🛡️ Graceful State Preservation |
| Run Reporting & Telemetry | ❌ No | ✅ JSON & Summary Reports |
| Configurable Thresholds | ❌ Single integer | ✅ Granular GuardConfig |
LongGuard runtime contracts are tested and verified under specific execution boundaries:
- Guarded LangGraph Resume (
compile_guarded_graph/GuardedGraph.resume): Supports explicit continuation for synchronous two-node graphs (START -> agent -> tools/END,tools -> agent) within the same controller process usingInMemorySaver. Async graphs, streaming, subgraphs, parallel tool dispatch, namespaces, and distributed checkpoint continuation are outside current support. - CrewAI Execution (
add_guard_to_crew): Explicitly bounded to the tested sequential, synchronous ReActCrewAgentExecutor. Async, hierarchical, batch, planning, memory, or native tool-batch modes fail clearly; callback-onlyCrewGuardremains available. - Detector Evaluation & Cost Tracking: Held-out detector evaluation metrics are provisional. Dollar cost estimation applies a 50/50 input/output token split when provider-specific token breakdowns are unavailable and is not an invoice billing guarantee.
- Non-Invasive Telemetry: Telemetry reports and checkpoints record execution history; they do not authorize replay or modify external service state.
See the full Tested Compatibility Guide for complete version matrices and verification details.
All behavior is customizable through GuardConfig:
from longguard import GuardConfig

config = GuardConfig(
    # Loop Detection Sensitivity
    tool_repeat_threshold=3,          # Repeated tool calls before reflection
    tool_repeat_window=6,             # History window to examine
    dead_end_threshold=5,             # Steps with no progress before triggering
    token_velocity_multiplier=3.0,    # Spike multiplier vs rolling baseline

    # Hard Safety Guardrails
    max_tokens_per_run=50_000,        # Hard stop if agent burns > 50k tokens
    max_steps=30,                     # Maximum steps permitted
    max_reflections=2,                # Maximum recovery attempts before kill

    # Dollar Cost Tracking
    model="gpt-4o",                   # Enables built-in cost estimation
    max_cost_usd=0.50,                # Hard-kill if run exceeds $0.50
    # cost_per_input_token=2.5e-6,    # Override for unlisted models (USD/token)
    # cost_per_output_token=10e-6,
)
👉 For detailed documentation on custom detectors, embedding backends, and LangSmith telemetry, see the Full Documentation.
LongGuard follows a structured, verified patch train to ensure production reliability:
- v0.2.1 – v0.2.4: Documentation truth, PyPI Trusted Publishing (OIDC), cross-platform CI (Linux/macOS/Windows × Python 3.11–3.13), and nightly framework compatibility canary.
- v0.2.5 (Current): Empirical performance baseline (p50/p95/p99 latency), link checking, and Feature Freeze.
- v0.3.0: Release Candidate multi-OS clean-environment verification and stable promotion.
- v0.4.0: Streaming guard and asynchronous execution parity (
asyncbreaker, async resume). - v0.5.0: Enterprise observability (OpenTelemetry semantic conventions, Prometheus metrics, structured logs, and alert sinks).
For full details, discussions, and milestone tracks, see GitHub Discussions and Project Milestones.
LongGuard is part of the Long Suite — a collection of tools for building, testing, and monitoring production RAG systems.
| Project | Description |
|---|---|
| LongParser | Document ingestion and chunking |
| LongTrainer | RAG chatbot framework |
| LongGuard | In-flight circuit breaker and reasoning loop recovery for agents (you are here) |
| LongCache | Semantic similarity cache for LLM and RAG pipelines |
| LongTracer | Hallucination detection and tracing |
| LongProbe | Retrieval regression testing |
Contributions are welcome! Please see CONTRIBUTING.md for guidelines on code formatting, running tests, and opening pull requests.
For vulnerability disclosures, please review SECURITY.md or contact technology@endevsols.com.
LongGuard is open-source software released under the MIT License.